If you have spent any time in an AI strategy meeting over the last year, you have probably heard someone mention RAG. It gets dropped into conversations the way "cloud migration" did a decade ago, as if everyone already knows what it means and nodding along is easier than asking. Retrieval-Augmented Generation, or RAG, is one of the more important ideas in applied AI right now, and understanding it does not require a computer science degree.
At its core, RAG solves a practical problem. Large language models are impressively fluent, but they were trained on a fixed body of data up to a certain point, and they have no built-in way to know what is happening inside your company today. RAG gives them a way to look things up before they answer. That shift, from an AI that only remembers to one that can also check, is why RAG has become central to how businesses actually deploy these systems.
It is worth saying early on that RAG works well in a demo and gets harder to run reliably once real data, real users, and real compliance requirements enter the picture. That gap between a proof of concept and a production system is where a lot of AI initiatives stall, and it is why enterprises increasingly look for a platform and a team of specialists who have already solved these problems, which is part of where a partner like ATC comes in.
What RAG Actually Is
RAG stands for Retrieval-Augmented Generation. Break the phrase apart and it explains itself reasonably well. "Generation" refers to what large language models like GPT or Claude already do: take a prompt and generate a coherent response. "Retrieval" is the new part. Before the model generates its answer, a separate process goes and fetches relevant information from an outside source, such as a company's internal documents, a product catalog, or a knowledge base, and hands that information to the model as extra context.
So instead of asking a language model "what is our refund policy" and hoping it remembers something from training data (which it almost certainly does not, since it has never seen your refund policy), a RAG system first searches your actual policy documents, pulls the relevant paragraphs, and feeds them to the model along with the question. The model then answers using that specific, current information rather than guessing from general knowledge.
How RAG Works, Without the Jargon
The mechanics behind RAG involve a few moving parts, and each one has a fairly intuitive job.
First, a company's documents, whether that is contracts, support tickets, product manuals, or internal wikis, get converted into something called embeddings. An embedding is a numerical representation of meaning. Two sentences that mean similar things end up with numbers that sit close together, even if the actual words are different. This is what allows a search to understand that "cancel my subscription" and "how do I stop my membership" are asking roughly the same thing, even though the words barely overlap.
Those embeddings get stored in a vector database, which is really just a specialized storage system built for finding "nearby" meanings quickly, rather than matching exact keywords the way a traditional search engine does. When a user asks a question, that question also gets converted into an embedding, and the vector database finds the stored documents whose meaning sits closest to it.
Those retrieved documents, usually the most relevant handful of paragraphs rather than entire files, get passed to the language model along with the original question. The model then generates its answer grounded in that retrieved material. It sounds involved when written out, but the underlying idea is closer to giving a well-read assistant a stack of the right reference material right before they answer your question, rather than asking them to answer purely from memory.
Why This Matters for Accuracy
Language models have a well-documented tendency to hallucinate, meaning they state something confidently that is simply not true. This happens because the model is predicting plausible next words based on patterns, not looking anything up. When a model does not know an answer, it often produces something that sounds right rather than admitting uncertainty.
RAG reduces this problem meaningfully, though it does not eliminate it entirely. By grounding the model's response in retrieved, verifiable source material, RAG narrows the gap between what the model says and what is actually documented to be true. It also makes answers auditable. A well-built RAG system can show which document a claim came from, which matters enormously in regulated industries or anywhere leadership needs to trust what an AI tool is telling employees or customers. This is closely related to a broader concern enterprises are grappling with as they roll out AI more widely, sometimes discussed under the umbrella of black box AI risks, where the inability to explain how a model reached an answer becomes a real barrier to adoption. RAG is one of the more practical tools available for closing that trust gap, since it gives the model something concrete to point back to.
Where RAG Shows Up in the Real World
The use cases for RAG are not abstract. Most businesses evaluating AI right now will run into some version of these.
Customer support is probably the most common entry point. Instead of a chatbot that can only answer generic questions, a RAG-powered support tool can pull from actual product documentation, past ticket resolutions, and policy pages to give specific, current answers. This is a large part of what is driving the growth of AI agents in customer service, where the difference between a frustrating bot and a genuinely useful one usually comes down to whether it has reliable retrieval behind it.
Enterprise search is another natural fit. Large organizations accumulate years of internal documents scattered across drives, wikis, and systems that do not talk to each other. RAG lets employees ask a plain-language question and get an answer synthesized from across that mess, rather than digging through folders manually.
Knowledge management follows a similar pattern. Onboarding new employees, answering compliance questions, or helping a field technician find the right procedure in the moment all benefit from a system that retrieves the exact relevant passage instead of forcing a manual search or, worse, an AI's unsupported guess.
Getting RAG From Proof of Concept to Production
This is usually where things get harder than expected. A RAG demo built on a few dozen documents can look impressive in a week. Scaling that same approach to hundreds of thousands of documents, across multiple business units, with proper access controls and audit trails, is a different order of problem entirely. Who is allowed to see which retrieved documents? How do you keep the vector database current as source documents change? How do you monitor model performance once it is live, and catch it quietly degrading before users notice? How do you deploy across the cloud environments a large enterprise actually runs on, rather than a single tidy sandbox? This is where sound AI governance frameworks stop being a compliance checkbox and become part of the actual engineering work.
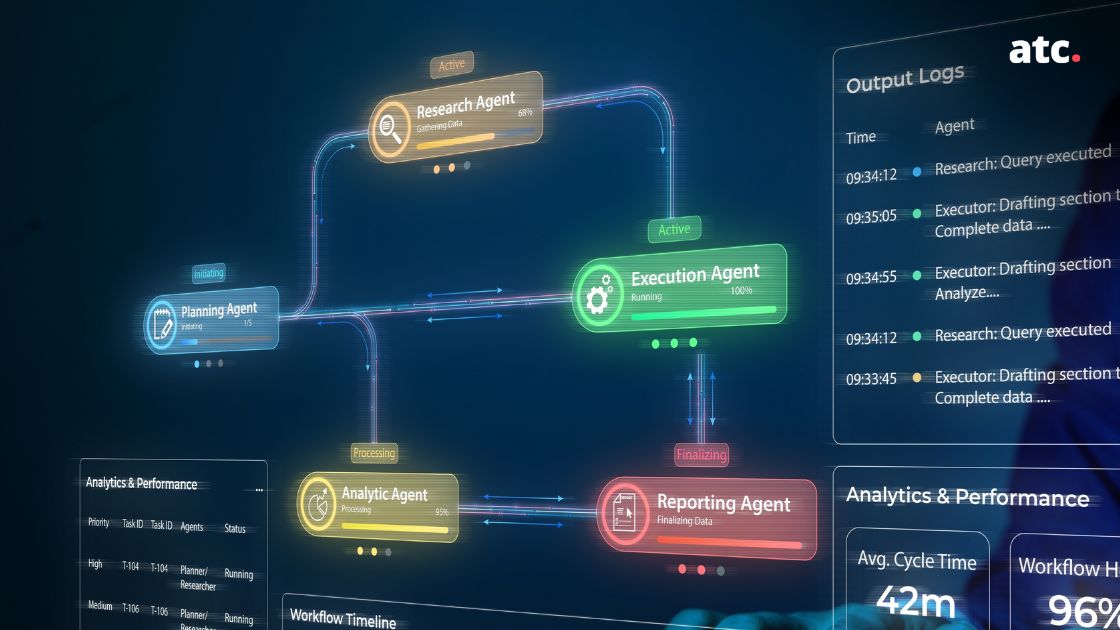
This is the layer ATC operates in. The ATC Forge Platform is built to handle these production concerns, with agent orchestration to manage how retrieval, reasoning, and action steps work together, more than 100 pre-built accelerators to shorten development time instead of building every component from scratch, and MLOps and LLM Ops tooling to monitor and maintain systems once they are live rather than letting them quietly drift. Governance is built in rather than bolted on afterward, and the platform supports multi-cloud and multi-LLM deployment, so organizations are not locked into a single vendor or a single model provider. Alongside the platform, ATC AI Services covers the arc of getting there: an initial assessment, rapid proof-of-concept development, deployment support to move from pilot to production, and 24/7 managed operations once the system is live and depended on. Put together, it is less about handing a company a single RAG tool and more about giving them the scaffolding to run RAG, and AI more broadly, at enterprise scale.
RAG's Place in the Bigger AI Picture
It helps to see RAG as one technique among several, not a replacement for the language model itself. Fine-tuning, where a model is further trained on a company's own data, changes how the model behaves or writes, but it is expensive to update and does not handle constantly changing information well. RAG keeps the underlying model untouched and simply changes what it is shown before it answers, which makes it far easier to keep current. Prompt engineering, meanwhile, is about how a question is framed, and it works alongside RAG rather than competing with it.
RAG also increasingly sits underneath more autonomous systems. As businesses move toward agentic AI, where systems take multi-step actions rather than answering single questions, reliable retrieval matters even more, since an agent acting on wrong information can cause real damage, not just an awkward chat response.
The Bigger Journey RAG Fits Into
RAG is genuinely useful, and understanding it puts a business in a better position to evaluate what its AI vendors and internal teams are actually proposing. But RAG is one piece of a much longer AI adoption journey, not the destination itself. Getting retrieval right is necessary, but it sits alongside decisions about governance, infrastructure, model selection, and change management that determine whether an AI initiative delivers value or quietly stalls after the pilot phase, a pattern well covered in a solid AI adoption framework.
Organizations that pair the right platform with a services team that has already navigated these production hurdles tend to move noticeably faster and with far fewer false starts. ATC's clients typically reach production 2 to 3 times faster than teams building from scratch, with a project success rate above 90 percent, precisely because the platform and the services wrap around the hard parts rather than leaving a team to rediscover them independently. If your organization is somewhere in the middle of figuring out how RAG, or AI more broadly, fits into your business, it is worth exploring how ATC's platform and services approach can shorten that path.
Subscribe to the blog